How the PR comment works
When an eval workflow finishes, evalship stores its results as a run for that commit, compares the run with a baseline, and reports the difference in a comment on the pull request and a check named evalship on the commit.
Every number in the report is computed by deterministic code. Failure patterns, likely causes and fixed review flaws come from rules where they can; a model writes eval notes and fills in what the rules can't (see the last section of this page).
Baselines
| The run is for | Baseline |
|---|---|
| A pull request | The run for the pull request's merge-base commit. If there is none, the latest run on the pull request's base branch; if there is none, the latest run on the default branch. |
| A push to the default branch | The previous run on the default branch. |
| A push to another branch | The latest run on the default branch. |
Without a baseline, the report lists the results with no comparison and says there's no baseline yet; a pull request with failing evals gets a first-pass comment. That's why the eval workflow must run on pushes to the default branch.
The default branch is GitHub's, unless your pull requests merge into another, such as dev with main for releases. Then pick that branch as Main branch on the repository's Settings page. Setup picks it for you when its own pull request targets that branch.
When a push to the default branch breaks evals that passed on its previous run, or stops evals that ran there from running (not a provider outage), account owners get an email: no pull request comment says so, and every pull request after compares with the broken results.
Change categories
Evals are matched by suite and key.
| Category | Meaning |
|---|---|
| 🔴 Newly failing | Passed in the baseline, fails now. |
| 🔴 Regressed | Same pass or fail state, and the score dropped by more than the tolerance. |
| 🟢 Newly passing | Failed in the baseline, passes now. |
| 🟢 Improved | Same pass or fail state, and the score rose by more than the tolerance. |
| 🆕 New | Not in the baseline. |
| 💤 Not run | In the baseline, not in this run: the run covered a subset (a tag, a filter, a path-filtered job). Counted, not compared. |
| 🔌 Couldn't run | Failed before it was scored: a missing API key (pull requests from forks and Dependabot get no secrets), a model the provider doesn't serve, a rate limit, a timeout, a provider or grader error. When the provider says the key hit its spending limit or ran out of credit, the comment says so in those words. Also an eval whose output is an HTTP error body or error page, even if it passed: the request never reached the model. And every eval in a suite failing with the same error line (not an assertion): the harness, provider or judge broke, not the answers. Not compared. A baseline eval that couldn't run is compared with the eval's latest earlier result on the default branch instead. |
| ⚪ Within chance | Would be newly failing or regressed, but its suite didn't get worse beyond chance (see below). |
| ⏳ Too early to tell | Would be newly failing or regressed, in a suite the default branch has run too few times to judge (see below). |
| ✏️ Eval changed | Would be newly failing or regressed, but the pull request changes no app code, only eval code and data, CI workflows and docs: the baseline's code fails its changed evals too. |
| 🟣 Flaky | Would be one of the first four, but the eval is flaky. |
| Unchanged | Everything else. |
Each eval is compared with its latest result on the default branch: the baseline's, or, when the baseline didn't run it, the newest of the 10 runs before it that did. A pass rate change is computed over the evals both runs have.
When the baseline isn't the run on the commit the pull request branched from (no eval ran there), and the comparison shows a change, the comment says so: changes merged in between count as the pull request's.
LLM evals pass and fail by chance, so a suite's newly failing and regressed evals count as regressions only when the suite got worse beyond chance:
- evalship measures the suite's noise on the default branch over its last 30 runs: how often a passing eval failed on the next run. Evals that passed every run are measured apart, on the newer half of their runs among evals that passed the whole older half, so they aren't judged by the suite's flaky ones. Runs from before a merged pull request changed how the suite is scored don't count: they measured another eval. Nor do failures 3 or more runs in a row: the eval broke, which isn't chance.
- More of the suite's passing evals must fail than that noise makes likely (or its scores must drop far more often than they rise), at a level chance would reach in fewer than 1 in 20 pull requests across the suites that ran.
- An eval that also failed on the pull request's previous push, or before a rerun of the same commit, counts, since failing twice after passing on the default branch is rarely chance. Unless it fails there often enough that twice in a row happens more than 1 time in 20.
- A suite whose scoring, model or grader this pull request changes keeps every regression: its noise is unknown.
- In a suite with fewer than 3 runs on the default branch (or since a merged pull request changed how it's scored), an eval that got worse is too early to tell, not a regression, until it also fails on the pull request's next push.
The rest are within chance: the comment still lists them, with how often each passed on the default branch, and says how many evals the suite usually loses between runs. One that runs a call the pull request changes is named with that call, since it may not be chance. Rerun them; failing again confirms them. With fail_on_new_failures on, evalship reruns the workflow itself, once, when an eval that passed every earlier run on the default branch fails, and the check waits for the rerun's results, for an hour at most. How noisy are LLM evals in CI? has the numbers behind this.
An eval that runs several times in one file with the same input (promptfoo --repeat) is one eval: it passes when at least half its repeats pass, and its score is their mean. Repeats that couldn't run (a rate limit, an outage) are left out. When both runs have repeats, the eval is judged on them: a drop in passing runs that Fisher's exact test can't tell from chance (3 of 3 to 1 of 3) is within chance, and a drop it can (10 of 10 to 6 of 10) is a regression even when most runs still pass. Every eval with repeats was tested, so a drop in an eval that still passes must clear the 5% divided by how many there are: alone, 10 of 10 to 6 of 10 counts; next to 3 other evals with repeats, it doesn't.
Evals with no result on the default branch (new, or not run there in the last 10 runs) can't be compared; one that fails is called out first. A suite whose evals all got new names is said once, not listed as new evals. A change within chance that leaves the eval passing (a score dip) is listed in the details only. A suite that runs only with a label isn't reported as not run on pull requests when its results arrived. When most evals here have no result on the default branch, the comment says how many were compared. Cost and time are compared over the evals both runs have, and only when each ran as many times on both sides. A suite renamed by the pull request (promptfoo names a suite by its description) is matched to the old name when they share at least half their evals.
When the result files name a different model, provider or grader for a suite than its baseline did (promptfoo records both), the comment says the suite's results aren't comparable.
The comment calls newly failing and regressed evals together "regressions", and newly passing and improved evals "improvements".
Tolerance
A score change counts only when the absolute difference is larger than the tolerance: 0.05 by default, configurable for the repository and per suite in .evalship.yml. With the default, a score going from 0.82 to 0.78 is unchanged; 0.82 to 0.76 is regressed. A flip between passing and failing always counts, whatever the score.
Flakiness
An eval is flaky when, over its last 10 runs on the default branch, it:
- passed and failed on the same code: a pull request's last run counts as a run of the code its merge puts on the default branch, when the merge changes nothing else,
- flipped between passing and failing at least twice, or
- has at least 3 scores whose standard deviation is more than twice its suite's tolerance.
Runs from before a merged pull request or a push to the default branch changed the eval's file, or code its suite exercises as the review lists it, don't count, so a fix stops reading as flaky once it lands. Nor do runs where the eval couldn't run, a whole suite failing on one error line included. Nor do 3 or more failures in a row: the eval broke, and passing again after is its fix, not a flip.
A flaky eval is usually a bug users hit some of the time, not noise: the baseline step and the eval's page give your coding agent instructions to find why it flips and fix it.
A flaky eval that changes gets a 🟣 row marked "flaky" in the status table and is listed under "Flaky, ignored" in the details. It stays out of regressions, improvements and the gate. The pass rate delta is then computed on the non-flaky evals. Set gate.ignore_flaky: false to turn this off.
The comment
Each new commit gets its report at the bottom of the pull request, below that commit. As soon as you push, the last report says it's outdated and collapses, so it doesn't read as the new commit's; once the new report is posted, GitHub hides the old one as outdated, one click away. Results for the same commit from another workflow or a re-run edit its report in place. To have one comment edited in place on every commit instead, set comment: { repost: false }. It comments only on open pull requests, and only with results for the pull request's latest commit. If you delete the comment, the next run posts a new one.
A comment for a pull request that shortened a system prompt and made judge errors fail:

evalship report
⚠️ Untested AI call: app/refunds.py#RefundPolicy.explain has no eval. Add one
| Eval | main | this PR | |
|---|---|---|---|
| 🔴 | $150 refund, $100 approved | ✅ 0.96 | ❌ 0.22 |
| 🔴 | $1,000 refund needs approval | ✅ 0.94 | ❌ 0.18 |
| 🟣 | Casual tone (flaky) | ✅ 0.81 | 🎲 0.62 |
🔍 2 failing evals promise a higher refund than the refund system allows, likely from the change to support_system.md. Liability risk
✅ Fixes "Evals pass when the judge is down" from your eval review.
💰 Eval run cost +30% ($4.10 to $5.34).
Details: 46 evals, 42 passed (-3 vs main@a1b2c3d)
| Suite | Passed | Mean score | vs main@a1b2c3d |
|---|---|---|---|
extractor |
12/12 | 0.98 | same |
summarizer |
13/14 | 0.89 | +0.01 mean |
support-bot |
17/20 | 0.82 | -3 passed, -0.09 mean |
🔴 Regressed
support-bot/ $150 refund, $100 approved: 0.96 to 0.22, passed, now failing (threshold 0.70)support-bot/ $1,000 refund needs approval: 0.94 to 0.18, passed, now failing (threshold 0.70)
🟣 Flaky, ignored
support-bot/ Casual tone: 0.81 to 0.62, passed, now failing (threshold 0.70)
🟢 Improved
summarizer/ Long thread: 0.78 to 0.91
💬 AI calls and prompts without evals
app/refunds.py#RefundPolicy.explainline 41 (openai)
Open the full report for every eval's inputs, outputs and history.
The parts, in order: the status line and suite bars, the status table, the notes, any .evalship.yml problems, the details, and the footer.
Status line and suite bars
The comment opens with an "evalship report" heading, its "report" linking to the full report, then two badges, this run's results and its eval flaws. When nothing broke and the review found no flaws, one line under them says so: "✅ All evals pass, no eval flaws found in this pull request." Otherwise the comment skips that line, because the table and notes below say what happened. The check's title always has it:
| Line starts with | When |
|---|---|
"2 regressions in support-bot, likely from …" |
Evals that passed on the baseline fail here, or an eval's score dropped by more than the suite's tolerance. Flaky evals don't count. |
"All 3 evals with no result on main fail here." |
Nothing broke, but evals with no result on the baseline fail here. They're new, not regressions. |
| "2 evals got worse, too early to tell from chance." | Evals got worse only in suites too young to judge (see Change categories). With regressions elsewhere, the line adds "2 more evals got worse, too early to tell from chance." |
| "No confirmed regressions." | Evals fail here about as often as they do by chance on the baseline. |
| "No regressions in the 46 evals that ran." | Some evals couldn't run, so they aren't compared. |
| "Nothing broke and 2 evals improved" | Evals that failed on the baseline pass, or scores rose. |
"All evals pass" or "Nothing broke; 2 evals fail as on main" |
Nothing broke, and every eval was compared. |
| "46 of 48 evals pass." | There is no baseline yet. |
It ends with what the review found: "2 eval flaws found in this pull request" or "no eval flaws found in this pull request".
The results badge shows passing evals out of the total for this run. It is red when the pull request broke an eval, yellow when evals fail that it didn't break or that it's too early to tell, and green when all pass.
The eval flaws badge counts what the pull request leaves your evals unable to catch: the model's notes on the diff, except Not comparable and a note on the change the failures are blamed on (shown as "Before you merge": whether that change is intended is your call, not a flaw in the evals that caught it), and changed AI calls or prompts that no eval runs here, except those a member dismissed. It is yellow when there are any and green at 0, and appears only once the model has read the diff, so a 0 is never a review that didn't happen. Each note it counts starts with ⚠️.
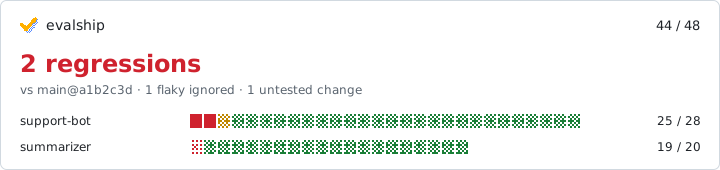
Below it is an image with one bar per suite, up to 6, the suites with regressions first, with passed and total and the change against the baseline. Each cell is one eval. A suite with no results in this run shows "no results here". The image links to the full report, and its alt text is the lead sentence. With one suite and nothing broken, the comment leaves the image out: the badge already says it.
| Cell | Meaning |
|---|---|
| Solid red | Regressed in this pull request. |
| Violet dither | Flaky, ignored. |
| Red dither | Failing, but not broken by this pull request, for example already failing on the baseline, or too early to tell. |
| Green dither | Passing. |
The badges and bars show counts and suite names only: no eval names, inputs or outputs. evalship serves them at /c/<token>.svg, a signed URL, so those of private repositories can't be guessed.
Status table
One row per change, worst first, up to 6 rows. The rest are listed in the details.
| Row | Meaning |
|---|---|
| 🔴 | A regression: the eval newly fails, or its score dropped beyond the tolerance. |
| ✏️ | An eval that passes on the baseline and fails with the pull request's eval changes, marked "eval changed". Not a regression: the pull request changes no app code. |
| 🆕 | An eval with no result on the baseline that fails here, marked "new", with "n/a" as its baseline result. Not a regression. |
| ⏳ | Too early to tell: the eval got worse in a suite the default branch has run fewer than 3 times, marked "too early to tell". Not a regression unless it fails on the next push too. |
| ⚪ | Within chance: a failure or score drop no worse than the suite's usual noise. See Flakiness. |
| 🟣 | A flaky eval that changed, marked "flaky" and left out of regressions; its score on this PR gets a 🎲 instead of a pass or fail mark. |
| 🟢 | An improvement: the eval newly passes, or its score rose beyond the tolerance. |
The last two columns show the result on the baseline and in this pull request: ✅ or ❌, followed by the score when there is one.
Notes
Up to 7 lines below the table, in this order:
| Note | Shown when |
|---|---|
| ⏳ Too early to tell | Evals got worse in a suite the default branch has run fewer than 3 times, so evalship can't yet tell the change from chance. Comes first, under the table rows it explains. |
| 🆕 New, failing here | Evals with no result on the baseline that fail here: they're new, or didn't run on the baseline's branch in its last 10 runs, so they aren't regressions. |
| ✏️ Not regressions | Evals that pass on the baseline fail with the pull request's eval changes, and it changes no app code: the baseline's code fails them too, so they show what to fix. |
| 🔌 Couldn't run | Evals that failed before they were scored, here or on the baseline, so they aren't compared. See Change categories. |
| 🔍 Failure pattern | 2 or more new failures fail for the same visible reason: the same failure message, or a reason the model names. Ends with the likely cause when one was found; a likely cause without a pattern gets a note of its own. At most 2 patterns. |
| ⚖️ Not comparable | The pull request swaps a model an eval runs or judges with (a model id in eval code or config, such as a harness default or a vitest.evals.*.config.ts), so results before and after measure different models. Only when a result moved against the baseline. |
| ⚖️ Scoring changed | The pull request removes or rewrites the line where a suite decides pass or fail (the scored_by line from your review), or deletes its file; or it changes code beside that line, adds a check beside it (an assert after it, not one in a new test), or changes code in a scorer's own file or in shared eval code the suite's file imports (a scorer helper); or it changes existing lines in the suite's data and prompt files (JSON, JSONL, CSV, YAML, TOML, text and Markdown) or lines of its code that state an expectation or threshold or a test case written as data (a quoted key or input and its expected values), such as relabelled test cases or an edited expected answer. Adding new test cases or tests, imports, and code moved unchanged to another file don't count. When the same pull request also changes a prompt that suite grades, the note says so: its test cases changed together with the prompt they grade. Its before and after results may not compare. Only when a result moved against the baseline, or when the suite doesn't run on pull requests, so nothing measures the change. |
| 💬 Untested | An AI call or prompt the pull request adds or changes that no eval exercises. See Untested changes. |
| 💬 Not run on PRs | An AI call or prompt the pull request changes is exercised only by suites that don't run on every pull request (by hand, on a schedule, or only with a label). See Untested changes. |
| ✅ Fixes a review flaw | The pull request changes a line a review flaw cites (or, for a missing test case, a suite's files), and every line it cites is gone, or the model judges that the diff fixes it (a missing test case is fixed by adding one). Links to the review. A flaw another merged pull request fixed first isn't counted again. |
| 🎲 Within chance | A suite's new failures that are within the noise measured on the default branch. See Flakiness. |
| 💤 Didn't run | A suite that had results in the baseline has none in this run. |
| ℹ️ Context | What else the comparison depends on: a young baseline, few evals with a result on the baseline, renamed suites. |
| 💰 Cost | Total eval cost changed by 20% or more, or total eval duration by 50% or more. Two bags once the cost doubles, three at four times. |
Fix instructions
When the notes include eval flaws, a collapsed block under them has fix instructions for your coding agent, every flaw in one prompt. Paste it in, or ask the agent to address the pull request's comments. Setup's own pull requests don't get one: setup fixes their flaws itself.
Details
Below the notes and fix instructions, a collapsed block starts with a summary like "Details: 46 evals, 42 passed (-3 vs main@a1b2c3d)". It contains:
- A table of up to 15 suites with passed evals, mean score (when a suite has one) and the change against the baseline.
- Lists of regressed (🔴), too early to tell (⏳), eval changed (✏️), flaky (🟣), within chance (⚪), improved (🟢), new (🆕) and removed (🗑️) evals, and of AI calls and prompts without evals (💬), up to 10 each.
- All failing evals, when there is no baseline and no pull request, such as the first run on the default branch.
A run of one suite with nothing to list gets no details block.
The full report on evalship lists every eval.
Footer
The comment ends with a link to the full report.
Once the default branch has results, the first comment that isn't a one-liner suggests the repository's badge for the README, once per repository.
When nothing changed
When there is a baseline and there are no regressions, untested changes, suites that didn't run, cost shifts or improvements, the comment is only its heading, badges, line and, with two or more suites, the suite bars:
## evalship [report](...)
[](...) [](...)
:white_check_mark: All evals pass, no eval flaws found in this pull request.
When some evals fail in both runs, the line says so: "Nothing broke; 2 evals fail as on main, no eval flaws found in this pull request." New passing evals, removed evals and flaky changes alone don't count as a change. To skip the comment in this case, set comment.only_on_change: true; a comment that already exists is still updated.
First pass
A pull request that sets the baseline gets a shorter comment: setup's own pull requests that add evals (branches starting with evalship/), a first run, or one where half or more of the evals are new, as long as some evals fail and nothing that had a result on the baseline broke, with these eval changes either. Its line says how many evals pass, that the ones that fail are where your evals start and not regressions, and that merging makes this the baseline later pull requests compare with. When the default branch already has results, it says instead which failing evals are new and which fail there too, and that merging records the new ones. Review flaws it fixes come first among the notes.
It has no suite image or status table. Its failing evals are listed once, collapsed, as "N evals to fix", up to 10, with the rest in the full report's "Failing" filter.
The full report
Every link in the comment opens the full report for the pull request on evalship. It follows the comment, one section per note:
| Section | What it shows |
|---|---|
| Status | The same badges and suite bars as the comment. A first pass also says why its failing evals aren't regressions, and failures that aren't regressions get their likely cause. |
| What broke | The failure pattern, the diff of the likely cause, and for each eval that broke: its input, what the model said on the baseline and in this pull request side by side, and why it failed. |
| Eval flaws | The model's notes that the eval flaws badge counts, and changed calls whose only evals don't run on pull requests. Each note links to its file and line and has fix instructions for your coding agent, which say to explain the risk rather than undo a change you made on purpose; with more than one, Copy all fixes next to the heading copies them as one prompt. The badge opens this section. Anyone with push access can dismiss a note as Wrong, Won't fix, Fixed or Later, saying why if they like: it leaves the count and the comment, on the pull request's later pushes too, and stays below the others, folded, until someone reopens it. One left for Later stays under Fix flaws until a pull request fixes it. |
| Untested | Each AI call or prompt the pull request adds or changes that no eval exercises, with its diff and a prompt to give your coding agent to add an eval. They can dismiss a file's untested calls the same way. |
| From your review | Review flaws the pull request fixes, with the diff that fixes them, leaving out those another merged pull request fixed first. The repository's dashboard marks them "Being fixed" while the pull request is open and "Fixed" once it merges. |
| Cost | Eval cost per suite, on the baseline and in this pull request. |
| All evals | Every eval with what changed, filterable by change, failing and suite. Each opens to its input, both outputs and its history on the default branch. |
The outputs come from your results file: the output property in JUnit (or <system-out>), or output in promptfoo and evalship JSON. See Result formats. See it on the demo repository.
The check and the gate
Every processed commit gets a check named evalship, whether or not it belongs to a pull request. On a pull request it shows as in progress from the push on, until the eval results are in. Its title is the lead sentence in plain text, or the one-line summary when nothing changed. Its output has the lead sentence, the status table, the notes, the gate result, on a first pass the evals to fix, the details expanded, and any .evalship.yml problems.
While the model writes its notes, a second check, evalship notes, shows as in progress, so you know to wait before you merge. It then says how many eval flaws the notes found, or why there are none. It never fails, so it never blocks a merge. With gate.fail_on_flaws, the evalship check waits for the notes too, and fails on their flaws (see Gate).
Lead sentence
| Situation | Lead sentence |
|---|---|
| No baseline, and not a first pass | "48 evals, 46 passing. Pull requests compare with main once it has results." |
| First pass | "46 of 48 evals pass. This is the first run, so there's nothing to compare with: the 2 that fail are where your evals start, not regressions. Merge this pull request, and every later one is compared with main's results." |
| Evals fail on a pull request that changes no app code | "2 evals fail with this pull request's eval changes, likely from …. It changes no app code, so they aren't regressions: they show what to fix." |
| New evals fail, nothing else broke | "All 10 evals with no result on main fail here. They're new, or didn't run on main in its last 10 runs, so they aren't regressions: …" |
| Regressions | "2 regressions in support-bot", with ", likely from ..." when evalship found a likely cause |
| Evals got worse in suites too young to judge | "2 evals got worse, too early to tell from chance." |
| Untested changes, no regressions | "No regressions, but this PR changes 1 AI call or prompt that no eval exercises." |
| Improvements only | "No regressions, 1 improvement." |
| Otherwise | "No regressions." |
When flaky evals changed, the lead ends with "1 flaky eval ignored."
Gate
The check is advisory by default: it concludes neutral, which never blocks a merge. It becomes a gate when .evalship.yml sets at least one of these:
| Key | Fails the check when |
|---|---|
gate.fail_on_new_failures: true |
Any non-flaky eval went from passing to failing, beyond chance, on a pull request that changes app code. In a suite the default branch has run fewer than 3 times, only once it fails on two pushes in a row. Also when evals that ran on the baseline couldn't run on a pull request that had the repository's secrets (not a fork's or Dependabot's), for a reason other than a provider outage. |
gate.fail_on_flaws: true |
The pull request has an eval flaw nobody fixed or dismissed, or changes an AI call or prompt whose suites run on pull requests and no results came for the commit. Dismissing a flaw in the report clears it. |
gate.max_pass_rate_drop: <points> |
The pass rate dropped by more than that many percentage points, leaving out flaky evals, failures within chance and evals failing with an eval-only pull request's changes. |
comparison.suites.<name>.required: true |
That suite has no results for the commit. |
With a gate, the check concludes success or failure, and a failure lists its reasons in the check: "🛑 Check failed: 2 evals went from passing to failing." To block merges, require the evalship check in a branch protection rule or ruleset.
With a gate, on a repository with a review, a pull request whose evals didn't run (a path filter, a label) still gets the check 30 minutes after its push, so a required check doesn't wait forever: neutral, or failed when a required suite sent no results or, with gate.fail_on_flaws, when it has open eval flaws or changes an AI call those suites test. The check is also neutral when evalship hits an error and for private repositories that aren't enabled. Use "Re-run" on the check in GitHub to process the results again.
Rules first, then the model
Rules settle what they can, the same way on every run:
- Failure patterns. 2 or more new failures whose failure messages share a first line once numbers are masked, labelled with that line, such as
fail with "Expected … tool calls, got …". A message under three words, such as a bare exception name, says nothing about why and isn't a pattern. - Likely cause. The one changed file the failing suites run: a prompt or AI call they cover, their scoring or test cases, or the model they use. When its diff removes or adds a single line, the cause quotes it. Two or more candidates, and the rules name none.
- Fixed review flaws. A flaw fixed by editing what it cites is fixed when every line it quotes is gone from the pull request's head commit, or its file is deleted. A line moved elsewhere in the pull request doesn't count. Flaws fixed by adding test cases or checks (untested instruction, untested prompt, thin dataset, a suite only judges grade) go to the model.
- Won't run. The pull request deletes the workflow that runs the evals, removes its
pull_requesttrigger, removes the results upload or itsif: always(), or addsif: falseto a step. The workflow is the one your review names, or any that names the results artifact. It also warns when GitHub skipped a workflow the pull request adds or changes that runs a suite's files, itsif:waiting on a label or a secret, so those evals never ran there.
On each pull request that changes prompts, AI calls, or eval code or data, touches a review flaw the rules couldn't confirm fixed, or has new failures the rules couldn't name or trace, evalship makes one call to a language model (today Claude Haiku 5.5, see Data and privacy), and after it merges, one more on the default branch's next run if it touched open review's flaws it couldn't confirm fixed. The first call gets:
- the pull request's title, the first 8,000 characters of its description, and its changed files;
- the diffs that matter for the evals, most relevant first: scoring files, eval code and data, files with changed prompts or calls, prompt files from your review, and CI workflows, up to 4,000 characters per file and 40,000 in all;
- your review's suites (path, what decides pass or fail, CI triggers, models, the code they exercise), its prompts, and its open flaws;
- up to 10 open notes from pull requests merged in the last 30 days, on files this pull request changes;
- once results arrive, the rows evalship computed and this commit's results;
- up to 20 newly failing evals (or evals failing with an eval-only pull request's changes), unless the rules already named and traced them: key, suite, and the first 600 characters of input and output and 400 of the failure message.
On a repository with a review, the call starts when a commit is pushed, while CI runs the evals, so the notes are ready when the results arrive. A commit whose results bring new failures is reviewed again then, with the results. A fork's pull request, which anyone can push to, gets its call once results arrive.
It can also read files and list folders in the repository at the pull request's head commit to check a note before it makes it: that an eval really doesn't load a file, that a fixture still returns what the test case expects. It returns up to 3 notes on what the change does to the evals, each shown in the comment with its label's emoji:
| Label | Meaning |
|---|---|
| ⚖️ Not comparable | The PR changes what an eval runs or how it scores (the model, a scorer, judge, threshold, fixture, or the inputs or expected answers of existing test cases), so its results won't compare with the base branch. Shown only when a result moved against the baseline. |
| ⚠️ Test cases changed | Test cases or expected answers change in the same PR as the prompt they grade, an expected answer is loosened, or a new test case can't fail on the bug it was added for. |
| ⚠️ Eval gap | The evals that cover the change can't catch it: they check something else, run a copy of the prompt, mock the call, or never load the changed file. |
| ⚠️ Makes a review flaw worse | The PR repeats or extends a defect an open flaw in your review describes. |
| ⚠️ Won't run | A suite or test case the PR adds isn't wired into CI, the PR stops a suite from running, or an eval gate it adds can't fail. |
| ⚠️ Eval note | Anything else material about the evals. |
| 🔍 Before you merge | A note on the change the failures are blamed on. Whether that change is intended is your call, so it isn't an eval flaw. |
When the rules couldn't name or trace new failures, it also returns failure patterns (groups of failing evals with a short label for what their outputs have in common) and, when the diff clearly supports it, the likely cause and the file it's in. It also says which of the review's flaws the diff touches, and the rules couldn't confirm, it fixes.
A note or pattern also says what the failure would cost, when the outputs or the rule show it: a Liability risk when a reply commits you to money, a price, a policy or a claim that isn't so; a Privacy risk when it shows one person's data to another or leaks a secret; a Safety risk when it could hurt someone, or an agent destroys or moves what it shouldn't. Each links to incidents of that kind in AI is never wrong. An eval gap on a new rule that code could enforce, such as a refund limit, also says to enforce it there.
evalship validates the answer:
- A note must name a file the pull request changed. A note that says it makes a flaw worse must name an open flaw.
- A pattern must name at least 2 of the keys given; unknown keys are dropped. At most 2 patterns are shown.
- A likely cause is dropped unless its file is one the pull request changed.
- Notes, labels and causes that contain a number not found in the input are dropped.
- Where the rules found a pattern, a cause or a fix, theirs stands; the model's notes come after the rules' own.
- A "Won't run" note about
continue-on-erroris dropped when.evalship.ymlsets a gate: then evalship's check is the gate, and the eval job staying green is the point. - Notes a repo member dismissed on an earlier push of the pull request go to the model with their reason, and it is told not to raise them again in other words; a "Wrong" reason corrects its reading of the code. A note of the same kind on the same file from a review written before the dismissal stays hidden; one the model writes after being shown the dismissal is a new note and shows. A rules note ("Won't run") stays dismissed on every push.
A rerun with the same results reuses the stored answer. The model is called at most 10 times a day for one pull request, and 20 times an hour for an account's public repositories. Without the call (no API key, over a limit, or the call fails or runs past its 8 minutes), the comment still shows everything the rules found.