Eval review for pull requests

Know what every PR does to your LLM evals.

evalship reads your eval results from GitHub Actions and comments on each pull request: which evals it really broke, the change that likely broke them, and which new prompts nothing tests yet.

Set up evalship: run `curl -sL https://evalship.com/setup.md` and follow the steps.

Paste into Claude Code, Cursor or Codex, inside your repo. Or sign in with GitHub.

evalship-appbot commented 2 minutes ago edited

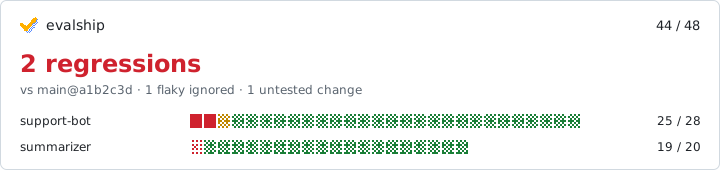
2 real regressions in support-bot, likely from the removed line "Always reply in the user's language" in prompts/support_system.md. 1 flaky eval ignored.

Eval main this PR
🔴 Refund question in Dutch ✅ 0.93 ❌ 0.41
🔴 Escalation in Dutch ✅ 0.88 ❌ 0.35
⚪ app/refunds.py#RefundPolicy.explain new LLM call no eval
🟡 Casual tone (flaky, ignored) ✅ 0.81 ❌ 0.62
🟢 Long thread ✅ 0.78 ✅ 0.91

🔍 2 of 2 new failures reply in English to Dutch messages, likely from the removed line "Always reply in the user's language" in prompts/support_system.md.

💰 Eval run cost +39% ($0.41 to $0.57).

👍 3🎉 1

01

Regressions, not noise

Evals that flip on main are marked flaky and set aside. What's left is what this PR broke.

02

The likely cause

evalship reads the diff: "2 of 2 new failures reply in English. This PR removed 'Always reply in the user's language'."

03

Untested changes

A new LLM call or a prompt edit that no eval exercises is flagged before it merges.

04

Advisory first

One comment, updated in place, and one line when nothing changed. The check blocks merges only if you ask it to.

A review of your evals

Things about your evals you didn't know.

During setup your coding agent reviews the evals: tests that can't fail, suites that only use an LLM judge, rules in a prompt that nothing checks. Every finding cites a file and line, and evalship checks each citation against your repo.

Important Untested instruction

Nothing checks the refund limit in the system prompt

The limit is a business rule; a prompt edit that drops it would ship silently.

  • prompts/support_system.md:12 Never promise refunds above 100 euros

Do this: Add two cases asking for refunds of 150 and 1,000 euros and assert the reply declines.

Notice Judge-only suite

All 28 support-bot assertions use an LLM judge

Judges cost about $0.01 per case and drift with the judge model.

  • tests/evals/test_support_bot.py:31 GEval(name="helpfulness"

Do this: Check order numbers and policy days with exact matches; keep the judge for tone.

README

support-bot

build: passing coverage: 91% evalship: 46 / 48 license: MIT

Customer support bot for Acme. Answers questions about orders, refunds and shipping in 12 languages.

In your README

A badge next to "build passing".

Live results from your default branch, on every PR comment and in your README. It turns grey after 14 days without results, so a stale green never lingers.

evalship: 46 / 46 evalship: 46 / 48 evalship: 31 / 48 evalship: stale

Free during the beta.
Public repos stay free.

Your coding agent does the setup in a few minutes. You approve every change.

Set up evalship: run `curl -sL https://evalship.com/setup.md` and follow the steps.